Public Relations AI Tools: The 2025 Playbook for Founders, PR Pros & Marketing Teams
PART 1 — The Collapse of the Old PR Stack (and What Replaced It)
Public relations tools are the data sources, distribution channels, monitoring systems, and workflows that teams use to find journalists, place stories, and measure reputational impact. In 2025 that category has been rebuilt: the winning stack is AI-native, real-time, and evidence-driven — not a static contact database with a send button bolted on.
💡 Key Takeaways
- Core Strategy: Treat media relations as a live data problem, not a list-management problem. Journalists, beats, and news cycles now change weekly — a quarterly-refreshed contact list is a liability, not an asset.
- Benchmark: The University of Princeton's generative engine optimization research found that adding verifiable statistics to content increased AI citation rates by 37%, and linking to authoritative sources added another 40% — evidence density is now a distribution mechanism.
- Execution Rule: Never pitch an angle you can't substantiate with a named source, a number, and a date. In an AI-mediated news environment, unsourced claims get filtered before a human ever reads them.
Why Traditional Public Relations Tools Are Failing Modern Teams
The legacy PR stack was built for a media economy that no longer exists: a world of thick newsrooms, predictable beats, stable staff email addresses, and wire services that functioned as a de facto distribution monopoly. Each of those assumptions has broken — not gradually, but structurally.
The supply–demand inversion: fewer journalists, far more pitchers
The defining arithmetic of modern PR is brutal. The number of people producing journalism has collapsed while the number of people pitching it has exploded. Pew Research Center's newsroom employment tracking has documented a sustained, decade-plus decline in U.S. newsroom jobs — a contraction that removed tens of thousands of reporting roles while the PR industry continued to grow headcount year over year.
The result is a market where a single technology reporter at a tier-one outlet may receive several hundred pitches a week. In successive State of Journalism surveys, journalists consistently report that the overwhelming majority of pitches they receive are irrelevant to their beat — frequently cited figures put irrelevance rates above 70%. That is not a messaging problem. It is a targeting problem, and it is structural.
Meanwhile, audience behaviour has shifted under the newsrooms' feet. The Reuters Institute's Digital News Report has tracked rising news avoidance, eroding trust, and — critically for PR — a reallocation of referral traffic away from search and social feeds toward AI assistants and closed platforms. A placement that generated 40,000 sessions from Google in 2019 may generate a fraction of that today, even at the same outlet. Reach is no longer a proxy for visibility.
Static databases vs. a moving media map
Here is the operational failure at the heart of most PR programs: the media database is a photograph, but the media is a video.
Every legacy database — and every spreadsheet built from one — is a snapshot of employment, beat assignments, and contact preferences captured at some point in the past, then resold. Between refreshes, reporters change outlets, get promoted, move from staff to freelance, abandon an inbox, or get laid off entirely. A database that is 90% "accurate" at the moment of compilation can be materially degraded within a quarter.
What does that degradation look like in practice? Bounce rates that quietly climb into double digits. Pitches landing in dead accounts. A founder's carefully crafted launch story routed to a journalist who left the publication eight months ago — while the actual beat reporter, hired three weeks ago, never sees it.
The legacy failure mode: You pay for access to a list. You then spend your most valuable hours — the hours you should spend sharpening the story — manually verifying whether the list is still true.
This is where a real-time approach diverges sharply. Pytch was built around a different premise: instead of licensing a stale index, it scans live news coverage — including Google News — to identify who is actually publishing on a topic right now, then reconstructs verified contact routes for those specific journalists. The distinction matters because it inverts the workflow. Legacy tools ask "who is on my list?" Real-time tools ask "who wrote about this exact topic in the last 72 hours, and how do I reach them?"
A quick comparison makes the gap concrete:
| Dimension | Legacy database workflow | Real-time AI workflow (e.g., Pytch) |
|---|---|---|
| Discovery | Filter a static index by beat keyword | Scan live coverage for who published on the topic this week |
| Relevance signal | Job title + outlet tier | Actual published output + angle adjacency |
| Contact data | Purchased record, refresh-cycle dependent | Reconstructed and verified per-journalist, per-campaign |
| Personalisation | Merge-field first name + outlet name | Hook built from the journalist's recent framing and gaps |
| Failure mode | Silent — you never learn the pitch bounced | Visible — delivery verification surfaces problems immediately |
The measurement gap: activity metrics masquerading as outcomes
The second structural failure is measurement. Most of the types of public relations tools in circulation were designed to report activity, not impact: impressions, ad-value equivalency, clip counts, share of voice. These metrics survive because they are easy to compute and flattering to present. They are also almost entirely disconnected from business outcomes.
Ad-value equivalency in particular has been discredited for years by practitioners and analysts alike, yet it persists in agency reporting decks because it converts an unmeasurable reputational effect into a large, impressive number. When a CFO asks what the $180,000 PR retainer produced, "42 million impressions" is not an answer. "Three enterprise pipeline conversations sourced to a single tier-one feature, closed at $420K ARR" is.
The State of the Media research has repeatedly found that practitioners cite measurement and attribution as one of their top persistent challenges — year after year, alongside securing coverage and demonstrating ROI. The tools changed; the gap didn't.
Workflow silos: five tools, zero shared context
The typical mid-market PR function runs a Frankenstein stack assembled over years: one vendor for media contacts, another for monitoring, a wire service for distribution, a spreadsheet for the media list, a shared inbox for outreach, and a dashboard that nobody trusts. Nothing talks to anything.
The cost isn't just licensing. It's context loss. The insight that a journalist just pivoted from funding rounds to AI regulation lives in the monitoring tool. The fact that this same journalist ignored your last two pitches lives in the outreach tool. The angle that performed in your last campaign lives in the analytics tool. No single system knows all three, so every campaign restarts from zero.
This is the hidden reason AI-native platforms are displacing point solutions: they don't compete on feature count, they compete on shared context. Discovery, personalisation, delivery, and measurement operating on one data layer means the system learns from every send.
Bad Pitch vs. Good Pitch: the same story, two outcomes
The difference between a pitch that dies and a pitch that lands is rarely the company. It's the precision of the targeting and the specificity of the hook.
❌ Bad pitch (generic, database-driven)
Subject: Innovative AI Startup Disrupts PR Industry — Interview Opportunity
Hi [First Name], I hope this email finds you well. I'm reaching out because our company, a leading AI-powered platform, is transforming how brands approach public relations. We're disrupting a $100B industry and would love to be featured in [Outlet]. We have a compelling story about innovation, growth, and the future of work. Are you available for a call this week? I've attached our press release and media kit.
Why it fails: no beat relevance, no news hook, no numbers, no evidence the sender read a single thing the recipient wrote. It is a press release wearing an email costume.
✅ Good pitch (real-time discovery, evidence-grounded)
Subject: Your piece on agency AI adoption missed the mid-market squeeze — data inside
Hi Maya — your Thursday piece on agencies piloting AI tools focused on the holding companies. The number that didn't make it in: mid-size agencies are cutting media-relations headcount 3x faster than they're adding AI tooling, based on our analysis of 1,400 agency job postings between January and September. That gap is where the churn is coming from. I have the dataset, the methodology, and a founder who ran a 90-person agency through exactly this transition and will speak on the record about what broke. Worth 15 minutes?
Why it works: it references a specific piece, adds a number the journalist didn't have, names a credible on-record source, and offers a 15-minute ask instead of a vague "call this week."
The good pitch is not a writing skill. It's a research skill — and research at scale is precisely what AI restructured.
The New AI-Powered PR Stack: Core Capabilities and Workflow
The 2025 stack is best understood as five layers, each replacing a legacy category of tool. Most teams are running a mix of old and new; the highest-performing ones have rebuilt layers 1 through 3 entirely.
Layer 1 — Real-time journalist discovery and relevance mapping
This replaces the media database. The core capability is temporal relevance: identifying not just who covers a beat, but who has published on a specific angle in the last days or weeks, and what argument they were making.
Scanning live news surfaces — Google News, RSS, outlet sitemaps, newsletter archives — produces a fundamentally different targeting graph than filtering a curated index. It captures new hires before the database refresh catches them. It captures freelancers, who are chronically underrepresented in commercial contact records. And critically, it captures momentum: a journalist who has written three pieces on AI procurement risk in six weeks is a far better target than one whose profile lists "enterprise software" as a beat.
This is the layer where Pytch does its core work: mapping live coverage to journalists to verified contact routes in a single pass, so discovery and outreach don't require a translation step between systems.
Layer 2 — Evidence-grounded hook crafting
The second layer replaces the manual pitch-writing grind. But the important distinction is between generic LLM output and retrieval-grounded output.
A model that hallucinates a trend is worse than no model at all — it produces plausible, unsourced claims that get a sender blacklisted. A model that is fed the journalist's recent coverage, your own proprietary data, and a set of verified third-party sources produces something different: a hook with provenance.
The Princeton research on generative engine optimization is the most quotable evidence here. Adding statistics to content raised citation rates by 37%; citing authoritative sources raised them by 40%. That finding was about AI search visibility, but it transfers directly to journalist behaviour — because journalists and language models are optimising for the same thing: can I verify this in 30 seconds?
The practical rule: every hook should carry one proprietary number, one named external source, and one specific reason this journalist specifically should care.
Layer 3 — Verified delivery and deliverability
Distribution is where good research dies quietly. The legacy stack treats sending as a solved problem — plug the address into the sequence tool and go. But an unverified address is not a delivery; it's a coin flip that costs sender reputation.
A modern layer does three things legacy tools skip: it reconstructs contact routes from multiple signals rather than trusting a single purchased field; it verifies deliverability before the send rather than discovering bounces after; and it surfaces delivery outcomes to the same system that did the discovery, so the targeting model improves on the next campaign. Founders who run cold outreach through generic sales-sequencing tools routinely torch domain reputation reaching press inboxes that were never valid in the first place.
Layer 4 — Coverage intelligence and AI-search visibility
Monitoring has expanded in scope. It is no longer just "did the article run?" It is:
- Coverage quality: sentiment, message pull-through, and whether the source was credited by name
- Share of voice: relative presence against named competitors in the same story cluster
- Answer-engine visibility: whether your brand, and your executives, are being cited when buyers ask an AI assistant about your category
That third item is new and increasingly non-optional. As Digital News Report data shows audiences migrating toward AI interfaces and away from feed-based discovery, the PR function and the AI-visibility function are converging into one job: getting your narrative into the corpora that machines summarise.
Layer 5 — Outcome measurement
The top of the stack converts activity into attribution. The mechanics are unglamorous: UTM discipline on every earned link, branded search lift tracked around coverage windows, self-reported attribution on inbound forms ("how did you hear about us?"), and CRM tagging that separates PR-sourced pipeline from paid and outbound.
A useful framing from executive-communication research published by Harvard Business Review: narratives win when they are simple, credible, and repeated by third parties. Measurement should test exactly that — did the narrative get repeated, by whom, and did the repetition move a behaviour?
Mapping the stack: types of public relations tools in 2025
For teams auditing their own setup, here's how the categories now map, including the often-overlooked edges of the discipline:
- Discovery tools — real-time journalist and outlet identification (replaces static media databases)
- Pitch intelligence tools — hook generation and personalisation grounded in retrieved evidence
- Verified outreach tools — deliverability-checked, journalist-first sending infrastructure
- Distribution and newsroom tools — owned newsroom, press page optimisation, embargo management
- Monitoring and listening tools — brand mentions, competitor coverage, narrative tracking
- Measurement and attribution tools — pipeline linkage, branded search lift, share of voice
- Public affairs tools — legislative and regulatory tracking, stakeholder and coalition mapping, policy-community engagement — a distinct discipline with its own data sources and longer time horizons
- Crisis and rapid-response tools — alerting, approval workflows, dark-site activation
A note on the last two: public affairs tools and crisis systems are often omitted from "PR software" roundups, yet they carry the highest stakes per decision. A regulatory tracking error or a delayed crisis response costs multiples of any efficiency gained in media list management.
Concrete public relations tools examples from current practice range from a live-news discovery platform feeding a three-person startup's first launch, to a full public affairs suite tracking committee hearings for a regulated enterprise. The basic public relations tools haven't disappeared — a media list, a press page, a monitoring feed — but each has been rebuilt around real-time data rather than periodic refresh.
The unifying principle across all five layers: the system must learn from the send. A campaign that doesn't update the targeting model is a campaign you'll repeat manually next quarter.
Part 2 breaks down the specific capabilities in detail — how to evaluate AI pitch tools without getting burned by hallucinated personalisation, the deliverability mechanics that separate inbox from spam, a step-by-step campaign build using a real-time stack from scratch, and the measurement model that finally connects earned coverage to revenue. If you want to see the discovery layer in action before reading on, you can run your first live media search on Pytch in under two minutes — start with a topic your competitors were quoted in this week and see who actually wrote about it.
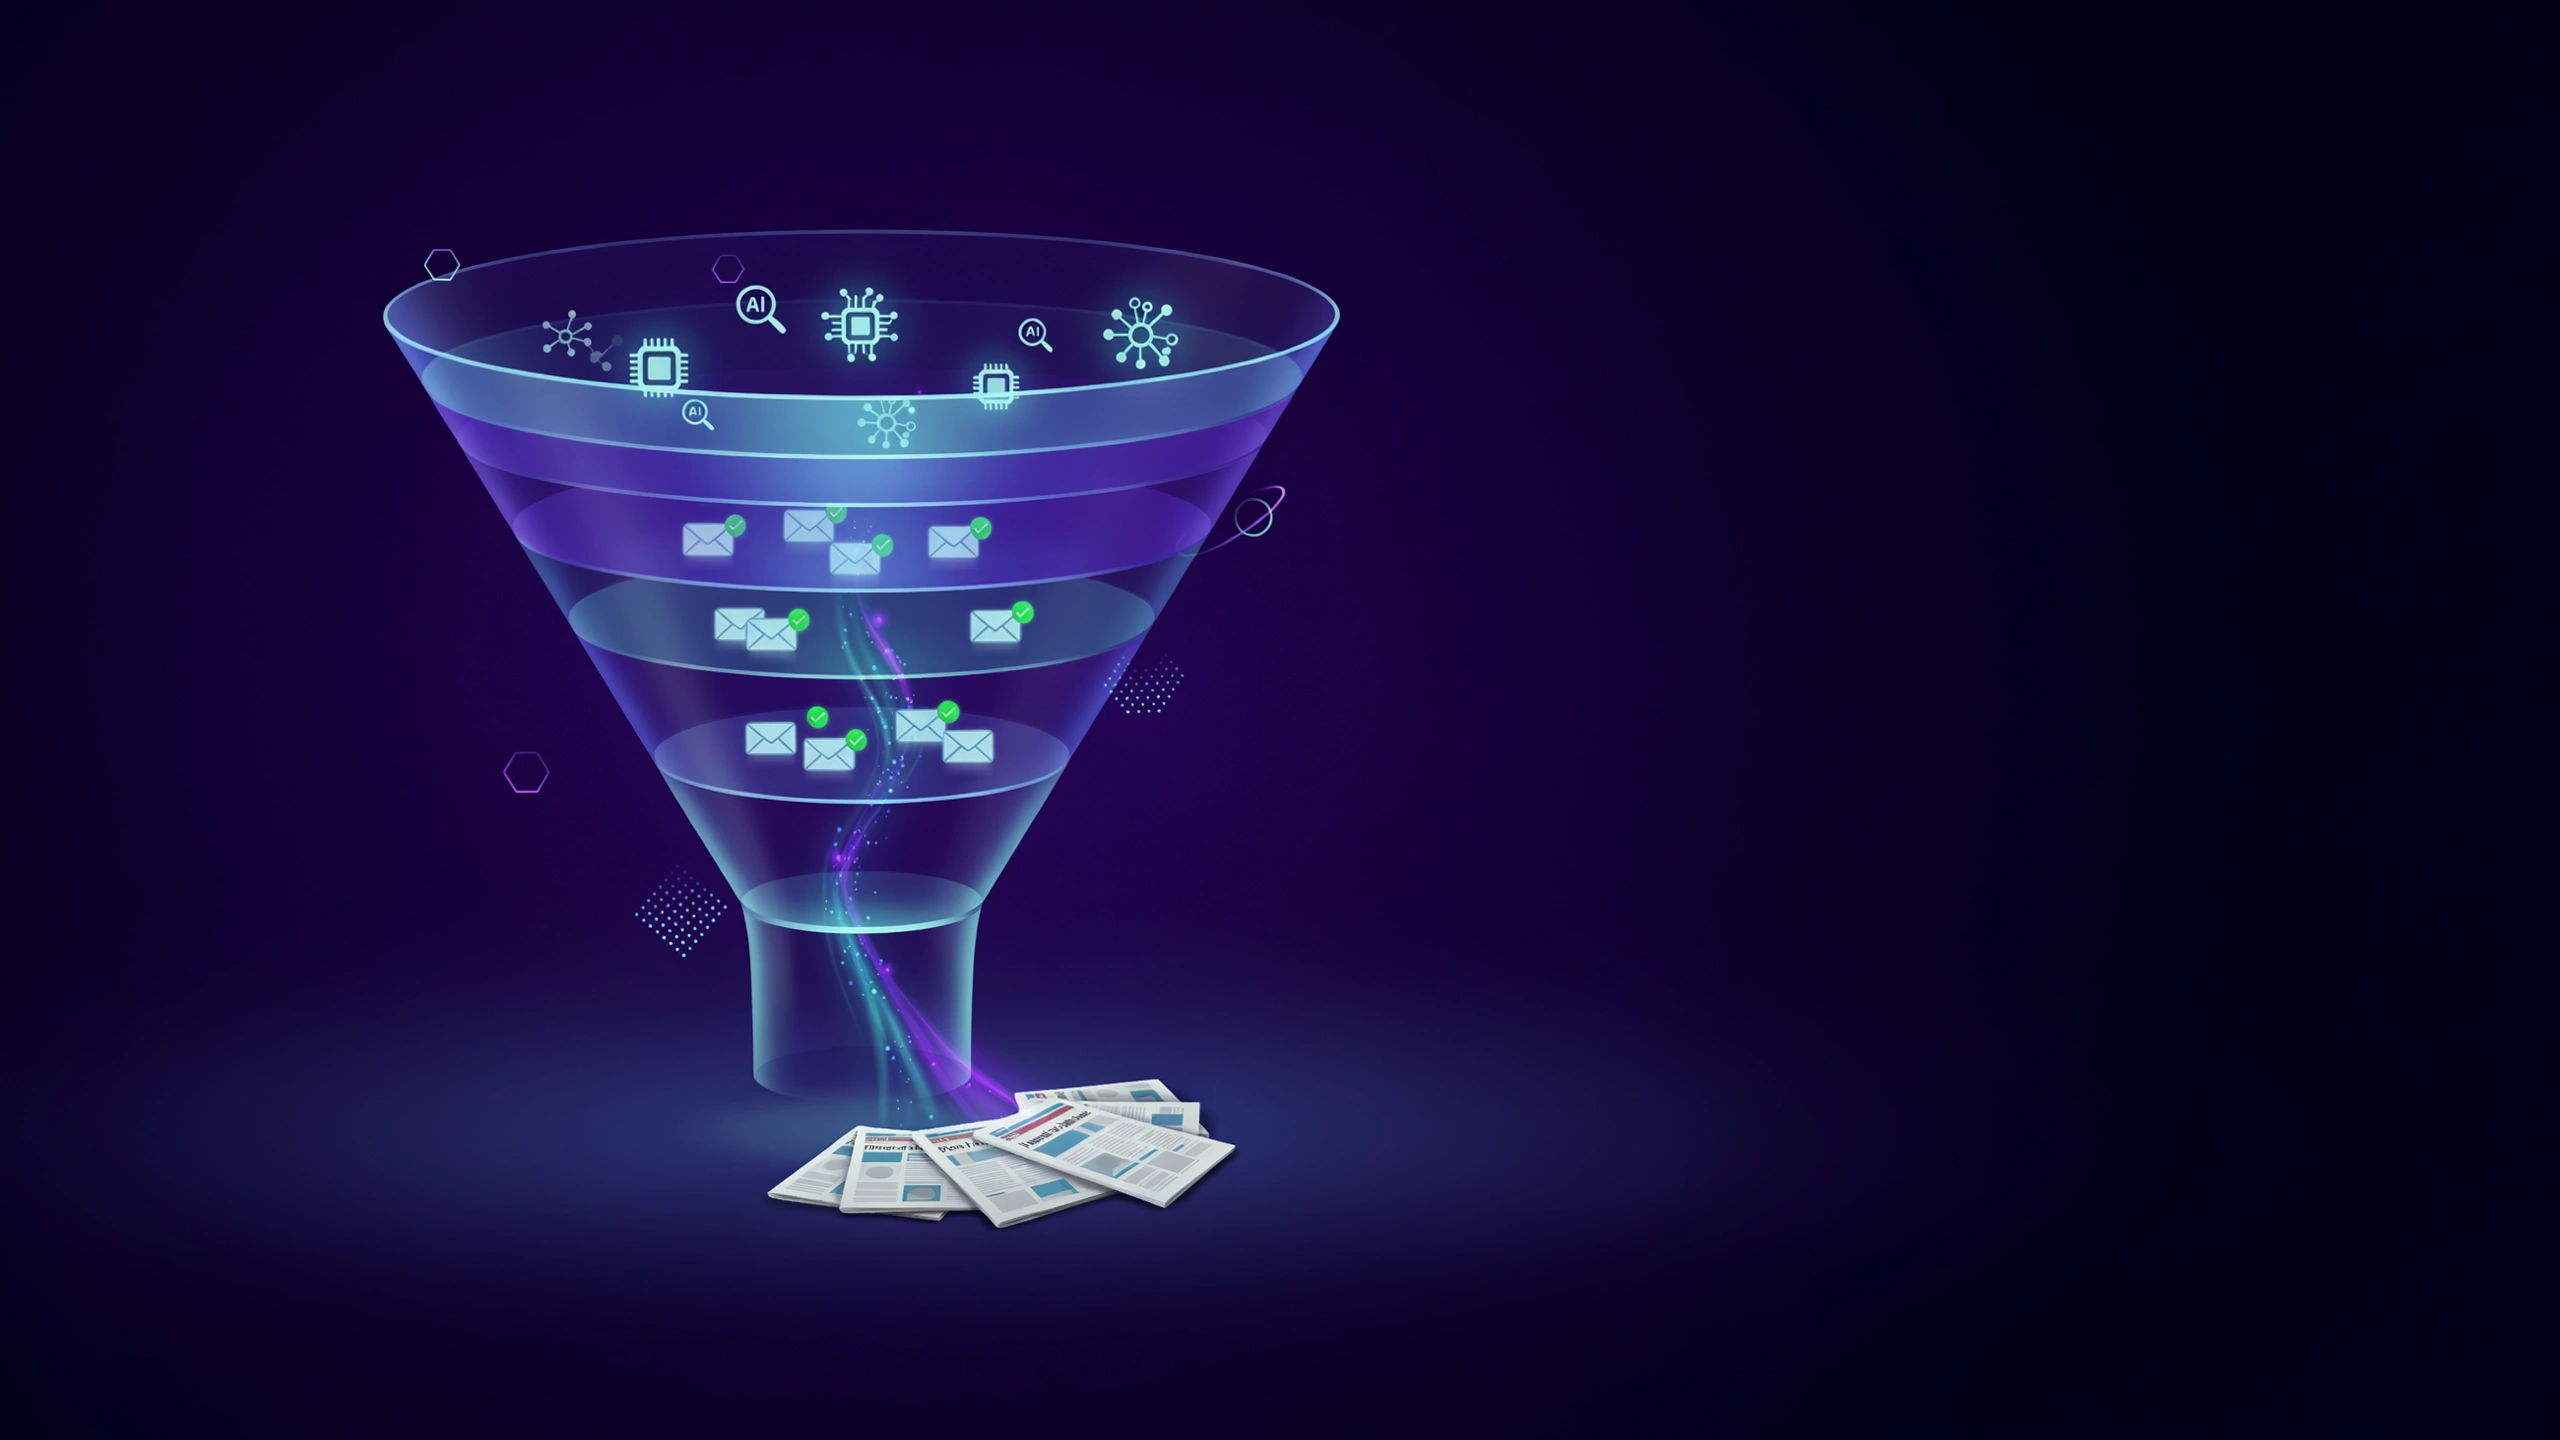
Figure 1: Strategic outreach framework and media targeting workflow.
Real-Time Journalist Discovery: From Static Databases to Google News Scanning
The discovery layer is where campaigns are won or lost — and it is the layer most teams still run manually. Here is the operating method, end to end.
The six-step discovery loop
Think of discovery as a loop that closes on itself, not a one-time list build:
- Define the story cluster (not the beat)
- Query live surfaces with operator syntax
- Score journalists on published behavior, not job titles
- Reconstruct and verify the contact route
- Send with a hook built from the article you found
- Log the outcome so step 3 gets smarter next cycle
Most legacy workflows execute step 4 only — they buy contacts and skip straight to sending. That's why the State of Journalism research keeps finding that the majority of pitches journalists receive are irrelevant to their beat. Irrelevance is a discovery failure, not a copywriting failure.
Step 1 — Define the story cluster, not the beat
"Enterprise software" is a beat. "AI procurement risk in mid-market healthcare" is a story cluster. Beats are too broad to filter on; clusters are narrow enough that publishing behavior becomes a reliable signal.
Build your cluster from three inputs:
- Your proprietary data — what number do you own that nobody else can publish?
- The adjacent news cycle — what did the category's reporters argue about in the last 14 days?
- The buyer's question — what would a procurement lead type into an AI assistant this month?
Write the cluster as a single sentence with a number in it. If you can't, the story isn't sharp enough to find journalists for.
Step 2 — Query live surfaces with operator syntax
This is the mechanical core of real-time discovery, and it's where most PR teams underinvest. Google News and outlet sitemaps support structured operators that let you slice coverage by recency, outlet, and headline keyword. A working query set:
intitle:"AI procurement" when:7d— who published on exactly this angle this week"AI procurement" source:TechCrunch— outlet-specific tracking for tech announcement formatting and embargo normssite:reuters.com "procurement" after:2025-09-01— long-window outlet sweeps for infrastructure reporters"AI procurement" -"press release" -"sponsored"— strip the noise that pollutes most keyword feeds
Run 6–12 queries per cluster, twice weekly. The output is a live coverage graph: article → journalist → outlet → date → argument. That graph is what a database can never give you, because it only exists after publication.
This is precisely the workflow where Pytch removes the manual translation step: it scans live news coverage including Google News, maps each relevant story to the byline behind it, and rebuilds a verified contact route for that specific person — in one pass, per campaign, rather than per database refresh cycle.
Step 3 — Score journalists on behavior, not job titles
Filtering by "senior correspondent, tier-one outlet" is a proxy metric that has been decaying for a decade. Score on observed output instead:
| Signal | What to measure | Why it predicts a reply | Weight |
|---|---|---|---|
| Recency | Days since last relevant byline | Journalists write in bursts; recent = active on the topic | 30 |
| Angle adjacency | Overlap between their argument and your data | You can add to a live thesis instead of starting cold | 25 |
| Cadence | Pieces on this cluster in the last 90 days | 3+ pieces = genuine beat ownership, not a one-off | 20 |
| Reach & authority | Outlet audience, syndication, citation frequency | Determines downstream pickup and AI-corpus ingestion | 15 |
| Contactability | Verified route + delivery signal | An unverified address is not a lead | 10 |
Set a hard cutoff at 65/100 and cap the list at 30–40 names per campaign. A 34-name list with a 70-point average outperforms a 400-name list every time — and protects domain reputation.
Rule of thumb: If you cannot name the last article the journalist wrote on the topic, they do not belong on the list.
Step 4 — Reconstruct and verify the contact route
Legacy databases resell a single purchased field. Modern practice treats contact as a reconstruction problem: cross-reference outlet staff pages, byline metadata, newsletter footers, conference speaker listings, and professional profiles, then verify deliverability before the send.
Three non-negotiables:
- Verify before send, never after. A bounce discovered post-send has already cost you sender reputation.
- Prioritise the route the journalist advertises. Many reporters explicitly publish the channel they prefer; ignoring it is a self-inflicted wound.
- Never route press outreach through a sales sequence tool. It appends tracking pixels, unsubscribe footers, and cadence logic that signal "mass marketer" to a press inbox.
Step 5 — Log the outcome and close the loop
Every send returns a data point: delivered, opened, replied, declined, ignored. Feed it back into the score. A journalist who replied once is worth 3x a cold contact; one who bounced is worth zero until re-verified.
This feedback loop — not the size of the index — is the compounding asset. It's also the structural reason AI-native platforms displace point solutions: discovery, verification, hook crafting, and outcome data sitting on one layer means the system learns your category's media map campaign over campaign.
The same launch, two workflows: a side-by-side
A concrete comparison using the same company, same news, same day.
The brief: A Series A fintech announces $14M, with proprietary data on SMB payment default rates.
| Phase | Legacy database workflow | Real-time AI workflow (Pytch) |
|---|---|---|
| 9:00 — List build | Filter 41,000 contacts by "fintech" + "payments"; export 412 names | Run 9 Google News queries on "SMB payment default," "embedded finance risk," "B2B payments AI" over 14 days |
| 9:45 — Shortlist | Manual spot-check of 40 profiles against LinkedIn; 7 already left | System returns 34 journalists with recent bylines, ranked by recency and angle adjacency |
| 10:30 — Verification | 26% of the export bounces on first send; 11% more on the second | 31 of 34 contact routes verified pre-send; 3 dropped, 0 bounces |
| 11:15 — Personalisation | Merge fields: first name, outlet, beat keyword | Hook generated from each journalist's last piece plus the default-rate dataset |
| 11:45 — Send | 380 sends via sequence tool; tracking pixels on | 31 individual sends, plain text, no pixels, Tue–Thu morning window |
| Outcome (7 days) | 2 replies, 0 interviews, measurable domain-reputation damage | 8 replies, 3 interviews, 1 tier-one placement, 2 newsletter pickups |
Same story. The delta isn't better writing — the copy was generated from the same source material. The delta is temporal relevance plus verified delivery. That is the entire argument for rebuilding the discovery layer of your public relations tool kit before you touch anything else.
The point generalises beyond one platform: whether you run this loop inside Pytch or assemble it from raw queries and a verification step, the operating principle is identical — discover from live output, verify before send, and let the result update the model.
The Anatomy of a High-Converting AI-Crafted Pitch
A pitch has six working parts. Miss one and the reply rate halves. AI is useful here only when it is constrained to fill these blocks with retrieved evidence — never to invent them.
The six-block skeleton
| Block | Job it does | Length |
|---|---|---|
| 1. Subject line | Signals specificity and stakes; survives the preview pane | 6–10 words |
| 2. Opener reference | Proves you read their work, by name and argument | 1–2 sentences |
| 3. The gap | Names what their piece missed, without insult | 1 sentence |
| 4. Your number | One proprietary statistic with methodology | 1–2 sentences |
| 5. The source | Named, on-record human who will talk | 1 sentence |
| 6. The ask | A specific, small, time-boxed request | 1 sentence |
Hard limit: 150–180 words total. Beyond 180 words, you are asking a journalist with 300 unread pitches to do homework. No attachments. One link maximum, and only if the link is the data.
Subject lines: the two patterns that work
- The corrective:
Your [Recent Article Title] missed the [Specific Angle] — data inside - The quantified claim:
[Specific Number]% of [Segment] are [Counterintuitive Behavior] — dataset available
Both work for the same reason: they make a falsifiable promise in under ten words. What fails is anything a competitor could have sent verbatim — "Innovative [Category] Startup Disrupts [Industry]," "Interview Opportunity," "Quick Question." In an inbox where the majority of pitches are already judged irrelevant, a generic subject line is a delete trigger.
Four templates worth keeping
Template 1 — The Data Gap Pitch (reactive, highest hit rate)
Subject: Your [Recent Article Title] missed the [Specific Angle] — data inside
Hi [First Name] — your [Day] piece on [Journalist's Argument] focused on [What They Covered]. The number that didn't make it in: [Proprietary Statistic]%, based on our analysis of [Sample Size] [Data Source] between [Start Date] and [End Date]. That gap is where [Consequence]. I have the dataset, the methodology, and [Named Source], who [Credential] and will speak on the record about [Specific Thing]. Worth 15 minutes?
Template 2 — The Contrarian Corrective (for analysts and columnists)
Subject: The [Widely Held Claim] doesn't hold in [Segment] — here's the cut
Hi [First Name] — you've argued [Their Thesis] twice this quarter ([Article 1], [Article 2]). Our [Sample Size]-[Unit] dataset says it inverts below [Threshold]: [Statistic]% of [Segment] do [Counterintuitive Thing]. Two explanations, one of which your [Prior Article] already half-anticipated. Happy to send the raw cut, no strings — or hold it for you exclusively if you want first look.
Template 3 — The Exclusive / Embargo Offer (tier-one only)
Subject: Exclusive: [Specific Number] [Segment] [Trend] — embargoed for [Outlet]
Hi [First Name] — offering you first look, embargoed until [Date/Time, Timezone], on [Story in One Clause]. Core finding: [Statistic]% of [Segment] [Behavior], versus [Comparison] a year ago. [Named Source], [Title] at [Company], is available for interview [Specific Window] and can speak to [Hard Question]. Full dataset and methodology under embargo on request. If it's not your beat, tell me who owns it and I'll route it there.
Template 4 — The Follow-Up (72 hours later, one only)
Subject: Re: [Original Subject]
Hi [First Name] — adding one thing rather than re-asking: [New Datapoint or Fresh Angle] landed since I wrote. If [Story] isn't live for you, no problem — is [Alternative Journalist / Adjacent Desk] a better fit? Either way I'll stop here.
The follow-up works because it adds information instead of repeating the request. One follow-up at 72 hours, then stop. A second chaser converts a warm non-response into a spam complaint.
The retrieval-grounded prompting loop
Generic LLM output fails in a specific, predictable way: it invents plausible trends. A model fed a journalist's actual coverage plus your actual data produces something categorically different — a hook with provenance. The Princeton generative engine optimization research quantified the underlying mechanism: verified statistics lifted citation likelihood by 37%, authoritative source links by 40%. Journalists and language models optimise for the same thing — can I verify this in 30 seconds?
Four inputs, every time:
- The journalist's last 3 relevant pieces, verbatim (headline + opening + thesis)
- One proprietary number, with sample size, methodology, and date window
- One named third-party source who will talk on record
- The ask — time-boxed and specific (15 minutes, one quote, one data cut)
Three guardrails against hallucinated personalisation:
- No number, no sentence. If a statistic can't be traced to your dataset or a cited report, it doesn't ship.
- Quote, don't paraphrase, the journalist's argument. Generic "I loved your recent piece" is a tell; a verbatim reference to their thesis is proof.
- Human review of every hook. AI should compress research time from 45 minutes to 4; it should never authorise a claim.
This is the "bespoke hook crafting" step in practice — and it's where Pytch pairs each shortlisted journalist with a hook drawn from their own published framing, so the reference is verifiable before it leaves the queue.
Deliverability mechanics: the part everyone skips
The best pitch in the world is worthless if it lands in spam. Email reputation is now a measurable infrastructure problem, not a copywriting one — Litmus's state of email research documents how consistently inbox placement drives engagement outcomes, and press inboxes are among the most hostile filters you'll encounter.
Non-negotiable configuration:
- Authenticate the domain: SPF, DKIM, and DMARC (p=none at minimum) on any domain used for outreach
- Separate the sending domain from your primary corporate domain until reputation is proven
- Cap volume at 20–30 sends per inbox per day. Rings alarm bells above that threshold
- Plain text only. No tracking pixels, no images, no HTML templates, no UTM-shortened links
- Send Tuesday–Thursday, 7:00–10:00 a.m. in the journalist's local timezone — before their filing deadline crush, after their morning read
- One link maximum, and only a direct link to the data or press page
Rule of thumb: Every unsolicited send that bounces or gets marked spam costs you the next fifty legitimate sends. Verify first; volume never compensates for a bad list.
Benchmark: what each outreach approach actually returns
| Outreach approach | Typical open rate | Typical reply rate | Coverage conversion | Best use case |
|---|---|---|---|---|
| Untargeted database blast (500+ recipients) | 15–25% | under 2% | under 1% | Never — reputation cost exceeds any upside |
| Beat-filtered database send (100–200) | 25–35% | 3–5% | 2–4% | Broad awareness, non-time-sensitive announcements |
| Real-time targeted pitch (verified route + recent-article hook) | 45–60% | 10–20% | 8–15% | Launches, proprietary data stories, founder access offers |
| Pre-briefed exclusive with embargo | n/a (single recipient) | 40–60% | 30%+ | Tier-one announcements with a hard news date |
| Cold sales-sequenced send to press inbox | under 15% | under 1% | ~0% | Never |
Figures are composite ranges drawn from State of Journalism research, Cision's media and credibility research, published outreach benchmarks, Pew Research Center's journalism data, and cold email performance data. Treat them as directional planning assumptions, not guarantees — your category and list hygiene will dominate.
The pre-send QC gate
Run these three checks before any pitch leaves the queue. Any failure sends it back.
- The 30-second verification test. Could a skeptical journalist verify your central number in half a minute? If not, add the methodology line or cut the claim.
- The substitution test. Swap in another journalist's name and outlet — does the email still read as plausible? If yes, it isn't personalised, it's templated.
- The reputation test. Is this contact route verified today, is the sending domain authenticated, and is the volume under 25 for this inbox?
Teams auditing their stack should map every one of these blocks to a named owner and a named tool before adding anything new. The most common failure in 2025 isn't missing software — it's a public relations software tools portfolio with discovery in one system, verification in another, and measurement in a spreadsheet nobody trusts.
The through-line: Real-time discovery tells you who, verified delivery tells you whether, and evidence-grounded hook crafting tells you why they should care. Build all three into one loop, and the public relations tools and strategies that felt like guesswork become an engineering problem with a measurable conversion rate.
Part 3 delivers the operational layer: the 30-day implementation checklist for rebuilding your stack, the deliverability audit that catches silent failures before they compound, the measurement model that connects a single placement to pipeline, and the FAQs founders and marketing leads ask most — including what to do when a pitch gets ignored, how to handle embargo breaks, and how to budget a real-time public relations media tools stack at seed, Series A, and enterprise scale.
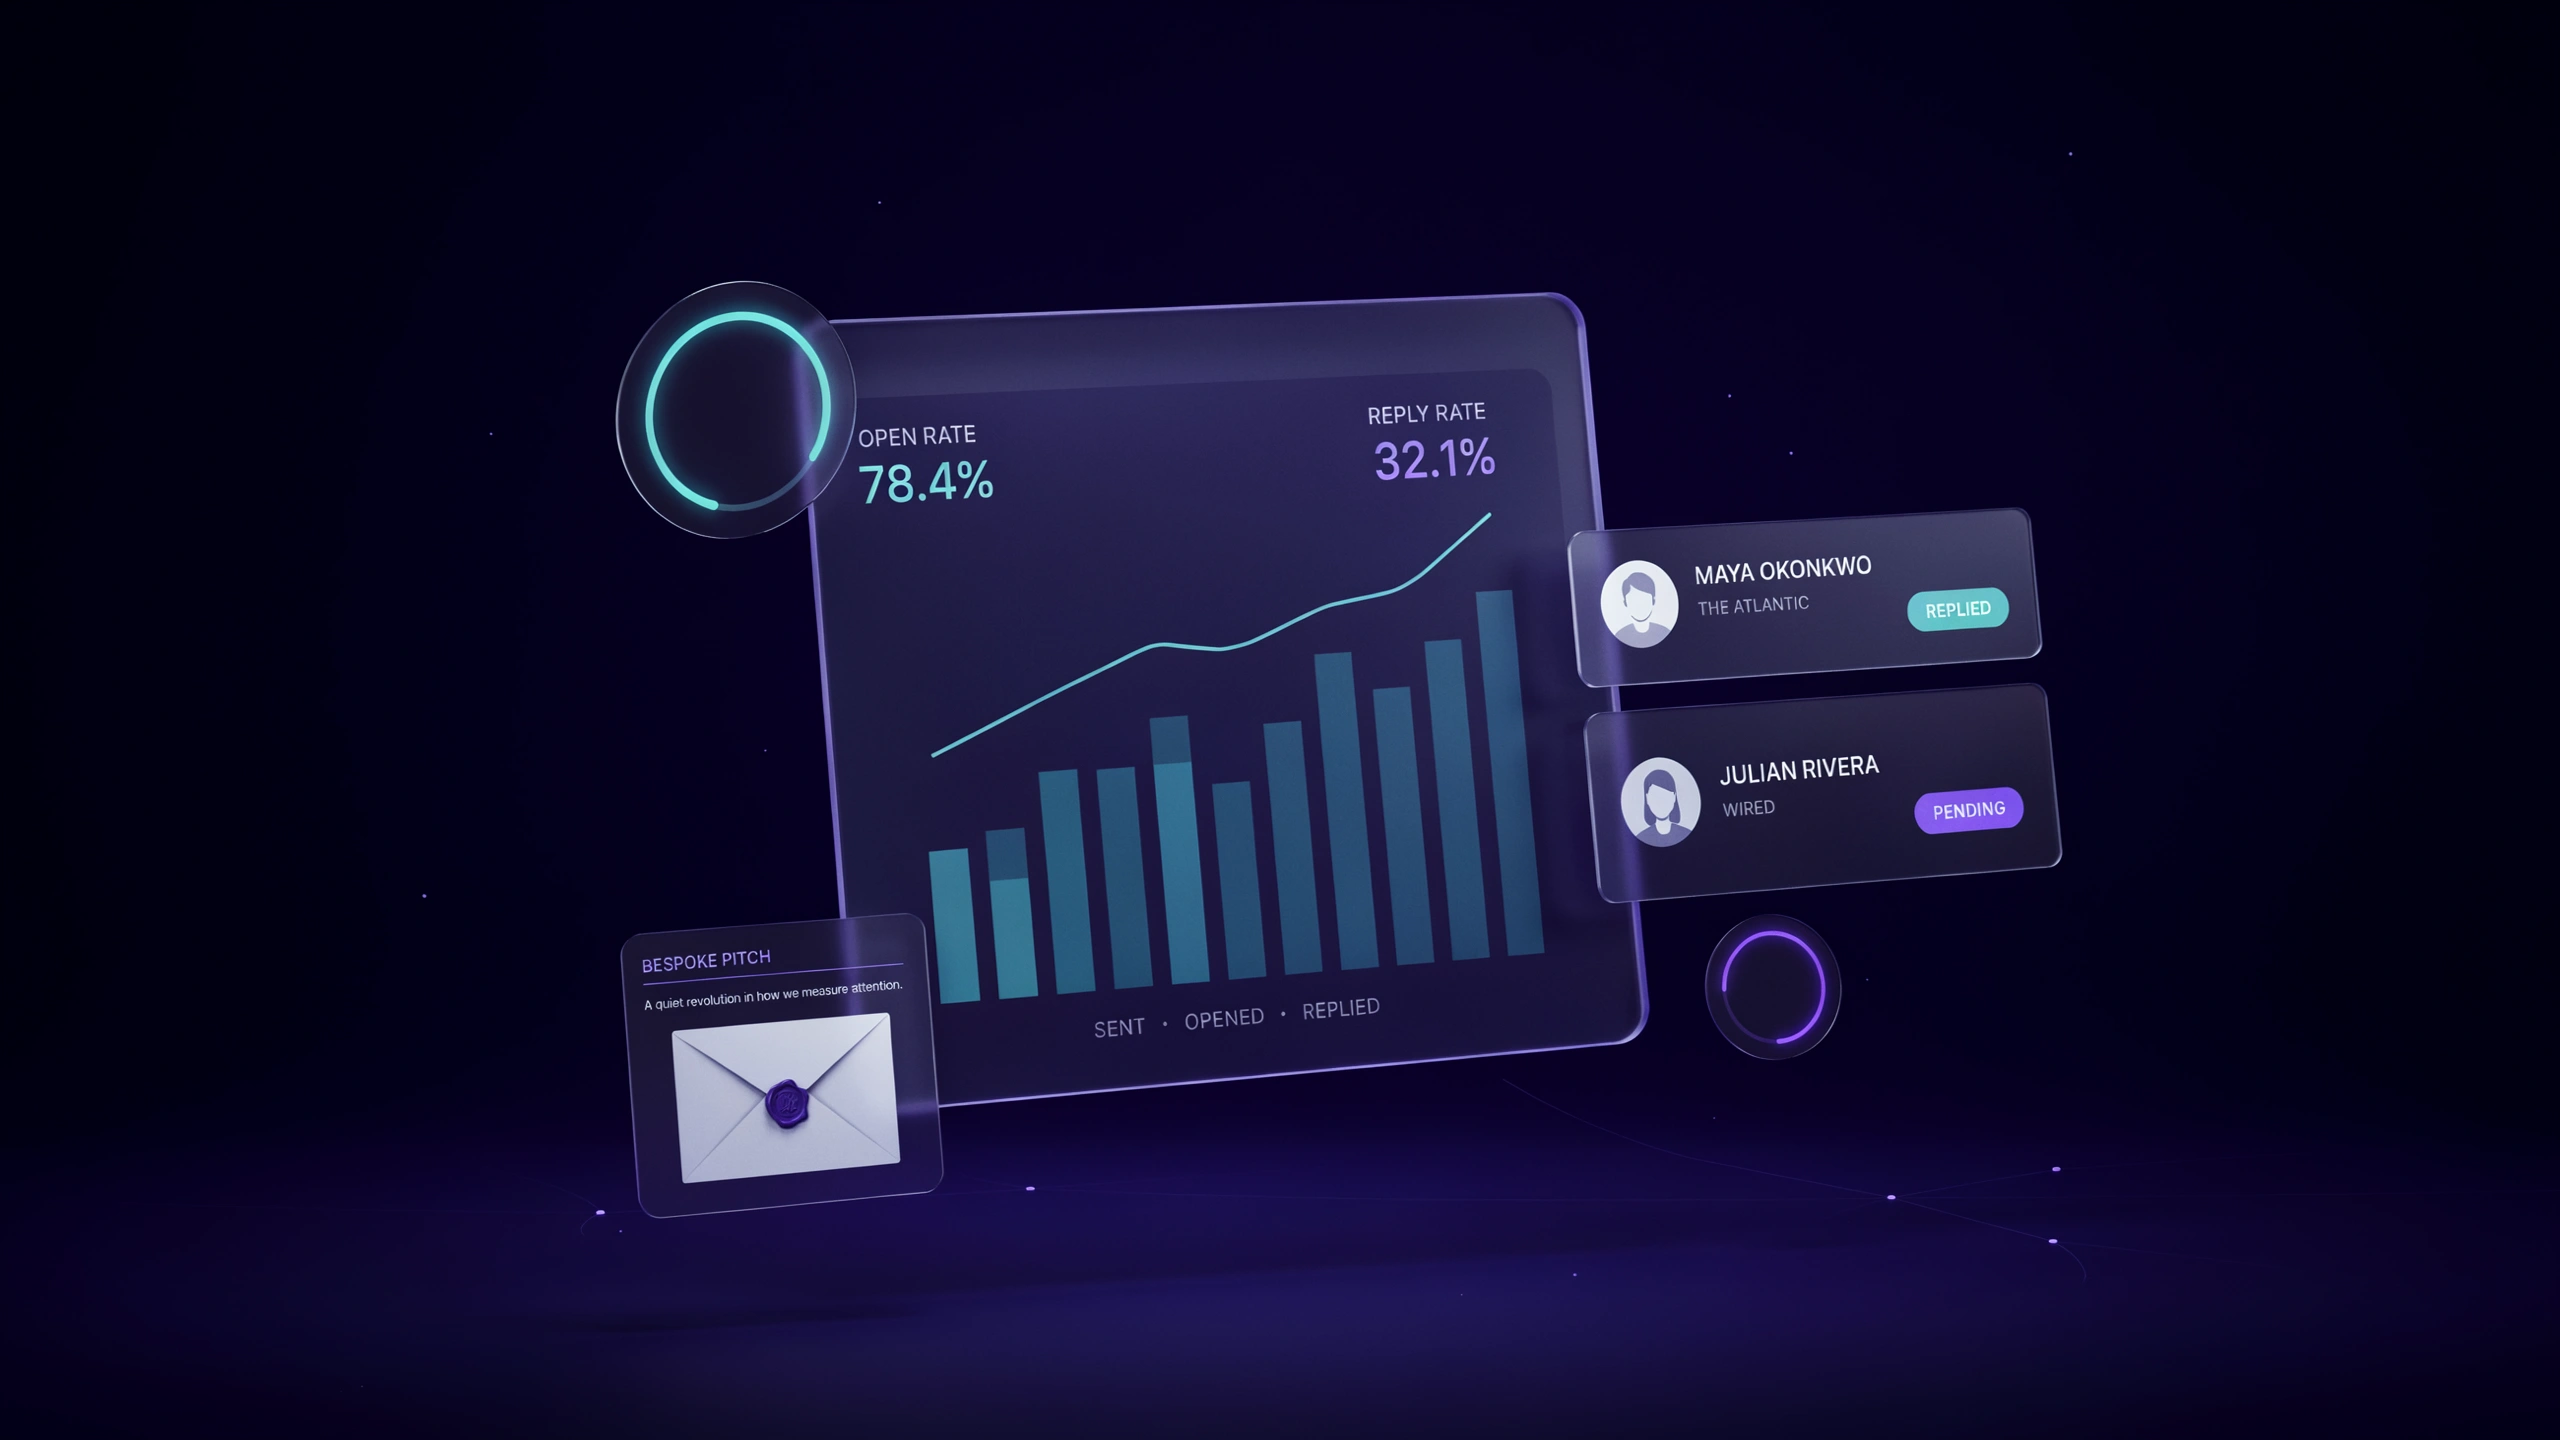
Figure 2: Performance metrics and response tracking across targeted outreach.
Critical Mistakes Founders & PR Teams Make (And How to Fix Them)
Every failure mode below has the same root cause: AI was deployed to accelerate an unverified process instead of to verify a process worth accelerating. Automation multiplies whatever you feed it — including bad targeting.
Failure 1 — Hallucinated personalisation: referencing work that doesn't exist
What teams do: Prompt a general-purpose model with a journalist's name and outlet, ask for a personalised opener, and ship the output. The model obliges with a fabricated reference — a piece from a rival outlet, a thesis they never argued, or a "recent article" from 2021 presented as current.
What it costs: This is the single most damaging error in the category, because it's visible. The journalist reads a paragraph about their own work and knows within four seconds that the sender never read a word of it. Research published by Princeton on generative engine optimization shows that verified, citable specifics lift citation likelihood by 37% — the inverse is equally true: unverifiable specificity destroys credibility faster than generic hedging ever could. Successive State of Journalism surveys report that the majority of pitches journalists receive are judged irrelevant to their beat; fabricated personalisation converts "irrelevant" into "bad faith," which is a permanent, unrecoverable classification.
The fix: Retrieval-ground every hook in verbatim source text — headline, opening line, and actual thesis from pieces published in the last 90 days. Three guardrails: no number, no sentence; quote, don't paraphrase; human review of every hook before it leaves the queue. This is exactly the constraint Pytch enforces by pairing each shortlisted journalist with a hook drawn from their own published framing — the reference is checkable against the live article before send, not generated from a model's memory of the web.
Failure 2 — Using AI to scale volume instead of precision
What teams do: Treat AI as a throughput multiplier. The reasoning is seductive: if a model can draft 400 pitches, send 400 pitches. Output volume becomes the KPI; reply rate becomes an afterthought.
What it costs: Two compounding damages. First, deliverability: high-volume sending to press inboxes from an unauthenticated or shared domain triggers reputation collapse, and once a domain is filtered, subsequent legitimate sends get caught too — Litmus's state of email research documents how directly inbox placement determines downstream engagement. Second, relational: tier-one reporters talk to each other, and a blast that reaches eleven reporters at the same publication simultaneously is a shared joke by lunchtime.
The fix: Cap the list. Thirty to forty names per campaign, scored at 65/100 or above on recency, angle adjacency, cadence, reach, and contactability. Volume never compensates for a bad list — and the arithmetic is unforgiving: a 34-name list converting at 15% outperforms a 400-name list converting at 1.5% on both replies and reputation.
Failure 3 — Treating a purchased contact field as a delivered email
What teams do: Export addresses from a database, plug them into a sales-sequencing tool, and hit send. The list is presumed true because it was paid for.
What it costs: Silent decay. Between vendor refresh cycles, reporters change outlets, move to freelance, abandon inboxes, or leave the industry. A database that is 90% accurate at compilation can degrade materially within a single quarter. The failure is invisible in the reporting dashboard — a bounce is logged as a bounce, not as a missed story — which is why teams keep repeating it.
The fix: Treat contact as a reconstruction problem, not a purchase. Cross-reference outlet staff pages, byline metadata, newsletter footers, conference listings, and professional profiles; verify deliverability before the send; route outreach through journalist-appropriate infrastructure, never a cadence tool with tracking pixels and unsubscribe footers bolted on. The moment you can see verification status per contact, the failure stops being silent — and silent failure is what makes legacy workflows expensive.
The distinction that matters: A static database is a photograph of the media. The media is a video. AI's job is to keep the frame current, not to send more copies of a blurred image.
Failure 4 — Pitching the company instead of the story
What teams do: Attach the press release, describe the product as innovative and disruptive, and ask for coverage. The company is the subject of every sentence.
What it costs: The journalist's only question is why now, why this outlet, and what does my reader learn? A company-centric pitch answers none of the three. This is the most common reason a technically valid, well-delivered email still generates zero replies. Executive-communication research from Harvard Business Review consistently points the same direction: narratives travel when they are simple, credible, and repeated by third parties — meaning the story must be built to be quoted, not to be admired.
The fix: One proprietary number with sample size, methodology, and date window. One named, on-record human who will answer a hard question. One sentence naming the specific gap in the journalist's recent coverage. If you cannot produce all three, you do not have a pitch — you have an announcement, and announcements belong in TechCrunch's embargo-and-format conventions, not in an inbox.
Failure 5 — Measurement theatre: impressions, AVE, and the absence of attribution
What teams do: Report impressions, ad-value equivalency, clip counts, and share of voice. None of these appear in a board deck unless the board is asleep.
What it costs: Budgets. The State of the Media research has repeatedly found that practitioners rank measurement and attribution among their top persistent challenges — year after year, alongside securing coverage itself. When PR cannot demonstrate pipeline contribution, it becomes the first line item cut in a downturn, regardless of actual effectiveness.
The fix: Instrument before you launch, not after. UTM discipline on every earned link, a branded-search tracking window around the coverage date, self-reported attribution on inbound forms, and CRM tagging that separates PR-sourced pipeline from paid and outbound. Then report in the CFO's units: pipeline created, influenced revenue, cost per qualified conversation.
Failure 6 — Blending editorial outreach with paid promotion
What teams do: Push sponsored content, affiliate offers, and paid placements through the same channel as earned-media pitches. The lines blur because the tools overlap.
What it costs: Editorial credibility, permanently. Journalists who discover they were pitched as a distribution channel for public relations promotional tools — sponsored placements, paid syndication, affiliate pushes — stop opening anything from that domain. These are separate disciplines with separate rules, separate data sources, and separate truth standards.
The fix: Physically separate the workflows. Earned-media outreach gets plain text, verified routes, evidence-grounded hooks, and a human reviewer. Promotional and paid-distribution activity runs through its own team, its own domain, and its own disclosure standards. Never let an automation layer decide which track an email belongs to.
Failure 7 — Over-automation: removing the human from the relationship
What teams do: Automate discovery, drafting, sending, follow-up, and reply handling end to end. The founder never reads a journalist's response until the calendar invite arrives.
What it costs: The thing PR is actually for. Coverage follows relationships, and relationships require a human who can improvise. An auto-reply to a journalist's question about methodology — sent by a sequence tool — is worse than a slow human answer three hours later.
The fix: Automate research and verification; never automate judgement or reply. AI should compress the 45-minute research pass into 4 minutes and stop there. Everything from the reply onward is human, and fast: a journalist's question typically has a 2–4 hour useful half-life before the story closes.
The Comprehensive PR Execution Checklist
Run the full sequence for every campaign. Assign an owner and a date to each line. Anything unchecked is a known risk, not a surprise later.
Phase 1 — Pre-Launch Prep (T-21 to T-7 days)
- Write the story cluster as one sentence containing one number. If you can't, the story isn't sharp enough to find journalists for.
- Inventory your proprietary data: sample size, methodology, date window, and the one figure nobody else can publish.
- Secure one named, on-record source for every claim — a founder, a customer, an operator who has lived the story.
- Build the query set: 6–12 Google News searches using
intitle:,when:7d,source:,after:, and noise-stripping negatives (-"press release",-"sponsored"). - Run the live coverage graph twice weekly for two weeks: article → journalist → outlet → date → argument. Save the output.
- Score journalists on recency (30), angle adjacency (25), cadence (20), reach (15), contactability (10). Hard cutoff at 65/100. Cap at 30–40 names.
- Reconstruct contact routes from at least three independent signals per journalist; prefer the channel the journalist publicly states they use.
- Authenticate the sending domain: SPF, DKIM, and DMARC at
p=noneminimum. Keep it separate from the corporate domain. - Warm the inbox for 10–14 days with low-volume, high-quality sends before the campaign goes live.
- Prepare embargo assets: full dataset, methodology doc, source bio, and interview availability windows with timezone clarity.
- Draft hooks using the six-block skeleton — subject, reference, gap, number, source, ask — under 180 words, zero attachments.
- Run the pre-send QC gate: 30-second verification test, substitution test, reputation test. Any failure returns to draft.
- Treat this infrastructure as public relations equipment — domains, verification layer, monitoring feeds, and a shared inbox are maintained assets, not software you browse once and forget.
Phase 2 — Outreach Execution (T-0 to T+3 days)
- Send Tuesday–Thursday, 07:00–10:00 a.m. in the journalist's local timezone — before the filing crush, after the morning read.
- Plain text only. No tracking pixels, no images, no HTML templates, no link shorteners. One link maximum, and only if the link is the data.
- Cap at 20–30 sends per inbox per day. Log every send against the journalist's score and hook variant.
- For exclusives: single recipient, explicit embargo date and timezone, and a clear "tell me who owns this beat if it's not you" escape hatch.
- Monitor delivery status in real time — verified route failures should be visible within the hour, not at the end of the week.
- Send exactly one follow-up at 72 hours. It must add information — a new datapoint, a fresh angle, or a routing offer to a colleague. Never re-ask.
- Answer any journalist question within two hours, with numbers attached. Speed is the most underrated variable in earned media.
- Keep running public relations tools notes — one living document recording what bounced, who replied, which hook variant converted, and what the journalist said they wished you had sent.
Phase 3 — Post-Pitch Nurturing (T+4 days to ongoing)
- Log every outcome — delivered, opened, replied, declined, ignored, bounced — and feed it back into the journalist's score.
- Re-verify any contact that bounced before it is ever used again. A bounced address is worth zero, not "worth retrying."
- Send a two-line thank-you to every journalist who replied, including declines. No pitch attached.
- Set a contact cadence of no more than once per six weeks per journalist, and only with genuinely new information.
- Record the story's structure in a reusable template library: subject pattern, hook structure, and source framing that converted.
- Instrument attribution within 48 hours of publication: UTMs on earned links, branded-search tracking window, inbound-form self-reporting, CRM tagging.
- Add the coverage to your AI-visibility baseline — check whether your brand and executives now appear when a buyer asks an assistant about your category.
- Run the post-mortem within 7 days: which score band converted, which hook variant won, and what the reply data says the media map looks like now.
- Update the coverage graph with new bylines from this cycle. The journalists who covered the category this month are your next cycle's list.
<!-- SEMANTIC_CLUSTER_START -->
H3: Pricing Tiers and Setup Economics — What the Best AI Tools for PR Actually Cost in 2026
Pricing models fragment the market into three buying patterns. Per-seat SaaS rewards headcount (fine for agencies, punitive for lean teams). Credit-based pricing on replies or sends aligns cost to output but punishes experimentation. Retainer-plus-license hybrids (the legacy agency model with a dashboard bolted on) remain the most expensive and slowest to deploy. When evaluating the best ai tools for pr, normalize every quote to a single metric: fully-loaded cost per verified pitch delivered. In 2026, most teams should model a 6–12 month window and assume 2027 pricing compresses further as autonomous agents replace manual seat licenses.
| Approach / Workflow | Cost (Typical 2026 Range) | Setup Time | Contact Verification | Reply Rate Impact |
|---|---|---|---|---|
| Legacy agency retainer + manual pitch | $5K–$15K/mo, flat | 2–4 weeks onboarding | Human-researched, 70–85% valid | Baseline (industry median ~3–5%) |
| Per-seat AI PR SaaS (research + drafting) | $150–$500/seat/mo | 1–3 days | Database + basic email check | +1–2 pts over baseline |
| Credit-based ai software for media relations | $0.50–$3 per verified send | Same-day | Waterfall verification (Bounceban/NeverBounce-class) | +2–3 pts with personalization |
| Autonomous agent (e.g., Pytch) + human QA | Usage-based, ~40–60% below retainer | Hours | Automated waterfall + inbox warmup | Highest where relevance is high |
Tactical callout: Budget the verification layer first. Sending unverified contacts through ai pitch writing and research tools is the single largest source of wasted spend in the modern ai pr tech stack.
Related search benchmarks covered: generative ai in public relations.
<!-- SEMANTIC_CLUSTER_END --> <!-- INTERNAL_CLUSTER_LINKS_START -->Related Playbooks in the AI PR & Automation Cluster
Explore connected guides in our AI PR & Automation semantic cluster:
- Pytch Ai Pr Agent: Pytch AI PR Agent: First AI PR Employee
- Pr Agency Vs Public Relations Software: PR Agency vs Public Relations Software: Which One Actually Earns Media in 2026?
- How To Use Pytch Ai Agent: How to Use Pytch: Public Relations AI Agent for Founder-Led Media Wins
- Free Pr Tool: Free Public Relations Tools in 2026: Introducing Pytch’s $0 PR Pre-Flight & Journalist Discovery Suite
Frequently Asked Questions About Public Relations AI Tools
Q: Can AI-written pitches get my domain blacklisted by journalists?
Yes — but the blacklisting mechanism is sender reputation and human memory, not the fact that a model drafted the copy. Gmail and Outlook filter on authentication, volume patterns, and complaint rates, while reporters maintain informal blocklists of domains that have wasted their time.
The distinction that matters is retrieval-grounded versus generative drafting. A model fed a journalist's actual last three articles, your actual dataset, and a named source produces a checkable hook; a model asked to "personalise this pitch for [Name] at [Outlet]" produces plausible fiction. The Princeton generative engine optimization research quantifies the direction of travel — verified statistics lifted citation rates 37% and authoritative source links 40% — because verification is what both journalists and language models optimise for. Practical mitigations:
- Human review of every hook; AI compresses research time from 45 minutes to 4, it never authorises a claim
- Separate sending domain, authenticated with SPF, DKIM, and DMARC
- 20–30 sends per inbox per day, plain text, no pixels
- One follow-up, at 72 hours, adding new information
- A hard rule that no statistic ships without a traceable source
Q: How much should a seed-stage startup budget for public relations AI tools?
Most seed-stage teams should plan $500–$1,500 per month for the discovery, verification, and monitoring layers combined — and spend founder hours, not agency retainer dollars, on the outreach itself. The reason is arithmetic: at seed, your proprietary data and founder access are your only differentiators, and both are free.
Where budgets go wrong is paying for access rather than precision. A $15,000/month agency retainer that produces impression reports is the worst value in the category; a $600/month stack that helps a founder run a disciplined 30-name campaign five times a quarter routinely outperforms it on placements. Recommended allocation:
- Discovery + verification: the highest-leverage line item — this is where targeting quality is decided
- Monitoring + AI-visibility tracking: start minimal, expand once you have coverage to monitor
- Distribution/newsroom: your own press page, properly structured, plus embargo infrastructure
- Reserve: 20% for opportunistic needs — trade press, public affairs tools if you're regulated, crisis alerting if you're consumer-facing
At Series A, the calculus shifts: budget for one dedicated person before you budget for more software.
Q: How do I connect a single media placement to actual pipeline?
Instrument the placement before it publishes — UTMs on every earned link, a branded-search tracking window around the coverage date, self-reported attribution on inbound forms, and a CRM tag that separates PR-sourced deals from paid and outbound. Then report in revenue units, not impressions.
The unglamorous mechanics are what make attribution defensible. Impression counts and ad-value equivalency survive in agency decks because they are easy to compute and flattering to present; they are also disconnected from how buyers actually arrive. Cision's media research has repeatedly ranked measurement and ROI demonstration among practitioners' top persistent challenges, which tells you the industry knows the gap and hasn't closed it. A workable model:
- Direct: UTM-tagged traffic → demo requests → closed-won, tagged
source: earned-[outlet] - Indirect: branded search volume in the 14 days post-publication versus the prior 60-day baseline
- Self-reported: "How did you hear about us?" on every inbound form, coded weekly
- Assisted: CRM opportunity records where a PR touch appears before the first sales conversation
Then ask the only question that matters: did the narrative get repeated by a third party, and did that repetition move a behaviour?
Q: Do I still need a traditional media database in 2025?
For most teams, no — a real-time discovery layer plus verified contact reconstruction replaces the core function, and a static index is a liability when it decays between refresh cycles. The exception is broad, non-time-sensitive awareness campaigns where a wide beat-filtered list is genuinely appropriate.
The reason is structural rather than vendor-specific. Databases are compiled from employment records and resold on a refresh schedule; publishing behaviour changes weekly. Live news surfaces — Google News, RSS, outlet sitemaps, newsletter archives — capture new hires before any refresh catches them, capture freelancers who are chronically underrepresented in commercial records, and capture momentum: a reporter who has written three pieces on AI procurement risk in six weeks is a categorically better target than one whose profile lists "enterprise software." This is the operating premise behind Pytch — scan live coverage, map each story to the byline, rebuild a verified contact route per journalist per campaign. What you should keep from the legacy stack:
- Monitoring and listening — still essential, now with AI-answer visibility added
- A CRM or lightweight tracking layer — outcomes must persist somewhere
- Your own accumulated relationship notes — the only list that compounds and never gets resold
Conclusion: Scaling Your Media Coverage with Pytch
The 2025 playbook reduces to one sentence: discover from live output, verify before send, and let every result update the model. Everything else — the six-block skeleton, the scoring rubric, the deliverability configuration, the attribution model — is implementation detail serving that loop.
What has actually changed is not the writing. Founders could always write a decent pitch. What changed is that the research step, which used to cost 45 minutes per journalist and therefore got skipped, now costs four minutes and can be done properly at scale. AI didn't make PR faster. It made precision affordable — which is a very different claim, and a far more durable one.
That shift has a commercial consequence most teams haven't priced in. As Reuters Institute's Digital News Report tracks audiences migrating from feed-based discovery toward AI assistants, a placement's value increasingly depends on whether your narrative enters the corpora those systems summarise. A tier-one feature that nobody cites in an answer engine is worth a fraction of one that gets absorbed into the category conversation. Which means the people best positioned for the next two years are the ones who quit asking "how many impressions did we get?" and started asking "did the right journalist repeat our number?"
That is the practical case for a real-time approach over a licensed index. A static database tells you who was on a beat. Pytch tells you who published on your exact angle in the last 72 hours, rebuilt into a verified contact route, paired with a hook drawn from their own framing — discovery, verification, and hook crafting on a single data layer, so each campaign's outcomes make the next campaign's targeting sharper. Not a bigger list. A list that's true today.
Three things to do this week, in order:
- Run one live search on a cluster you actually own. Not your company name — the argument your data can settle. Look at who wrote about it in the last 14 days. Note how many of those bylines were not in your current list.
- Verify the routes before you write anything. Check DMARC on the domain you send from. Confirm the addresses resolve. A campaign with 30 verified contacts beats 300 unverified ones on every metric that reaches the board deck.
- Send one pitch that would survive the substitution test. If you can swap in another journalist's name and the email still reads as plausible, rewrite it until that's impossible.
Then let the loop run. Log the replies, re-score the contacts, re-scan next week. Media relations stops feeling like guessing once the feedback loop is closed — and the compounding starts in the second campaign, not the first.
<!-- SEMANTIC_CLUSTER_UPGRADED_V2 -->Start here: Run your first live media search on Pytch — under two minutes, no list to buy. Search the topic your competitors were quoted on this week and see exactly who wrote about it, what they argued, and how to reach them. The journalists already telling your story are easier to find than the ones you were about to pitch cold — and they're the ones most likely to answer.